Several years ago, I wrote a blog article introducing the concept of code coverage for semantic models: Part 8: Bringing DataOps to Power BI. With the state of Power BI technology at the time, the bridge was a little far and implementation was quite arduous.
That has changed. With Power BI Project files and User-Defined Functions becoming generally available in 2026, we now have detailed inspection possibilities with what tests exist, what specifically is being tested, and where the gaps in testing live.
I’m happy to announce that version 0.1.18 of pql-test introduces our first attempt at code coverage for semantic models: pql-test code-coverage. Maybe you’re asking, why would you even do that? With AI advancing the changes to our semantic models in both speed and scope, making sure those changes are tested, and knowing what aspects are not tested, is vital to the long-term health of the model.
We’re very interested in feedback on this concept of code coverage for semantic models. Below is our one-page write-up on pql-test code-coverage to learn more.
TL;DR
code-coverage reports dependency coverage, not assertion coverage. An object (table, column, measure, relationship, partition, role) counts as “covered” only when a discovered .Tests.dax UDF has direct, verifiable evidence that it touches that object. It is never counted as covered because a test reaches it indirectly through a shared PQL.Assert. helper function, and never inferred from multi-hop dependency chains.
At a high level, the process works like this:
- Discover test UDFs using
PQL.Assert.RetrieveTestsV2(). - Inventory eligible objects via
INFO.TABLES,INFO.COLUMNS,INFO.MEASURES,INFO.PARTITIONS, andINFO.RELATIONSHIPS, plus roles. - Collect direct evidence for each object, following the per-category rules below.
- Classify every object as covered, a gap, or excluded.
- Report the results as text or JSON, and optionally fail the run if coverage falls below a
--min-coveragethreshold.
Why “direct evidence” instead of “reachable”
Every DAX test UDF calls shared helpers like PQL.Assert.Col.ShouldExist. If coverage simply asked “can this object be reached from the test at all?”, every object touched by any helper call elsewhere in the model would look covered. That’s not a meaningful signal.
pql-test avoids that trap by reading INFO.CALCDEPENDENCY(), a flat, one-row-per-edge dependency graph for the whole model, and keeping only the first hop, where OBJECT is literally a discovered test name.
Picture a test named Schema.DEV.Tests. It has direct edges to a table, a column, and the PQL.Assert.Col.ShouldExist helper function, and each of those counts. But if that helper function references another column internally, that’s a second hop, and it does not count. A chain like test → helper → object produces two separate rows in INFO.CALCDEPENDENCY(). Filtering OBJECT down to the set of discovered test names naturally keeps the first row and drops the second, no AST or text parsing needed for tables, columns, or measures.
Per-category evidence sources
Not every object type leaves a usable edge in INFO.CALCDEPENDENCY(), so each category has its own verified evidence rule:
| Category | Evidence source | Never counted as |
|---|---|---|
| Table, calculated column, measure | Direct INFO.CALCDEPENDENCY() edge from a test UDF | Covered via a transitive/indirect reference |
| Relationship | Test UDF’s own DAX expression text contains a literal PQL.Assert.Relationship.ShouldExist(fromTable, fromCol, toTable, toCol) call matching a real relationship | Covered just because the test calls the helper with some arguments |
| Role | Test UDF’s PQLAssert_RoleName annotation matched against ROWS_ALLOWED rows for that role | Covered without the annotation present |
| Partition | n/a | Never covered or uncovered; always excluded, since no assertion surface exists |
Classification and reporting
When you run pql-test code-coverage, the CLI connects to the semantic model over XMLA and discovers the test UDFs with RetrieveTestsV2(). It then queries INFO.TABLES, INFO.COLUMNS, INFO.MEASURES, INFO.PARTITIONS, and INFO.RELATIONSHIPS, along with the full edge graph from INFO.CALCDEPENDENCY(). If a category’s metadata query fails, that category is reported as unavailable rather than silently scored as zero.
From there, the eligible objects, direct evidence, and exclusions are handed to the classifier, which sorts everything into covered, gaps (with AI test-target hints to help you close them), or excluded. The report renders the overall percentage, a per-category percentage, the evidence behind each, and the gaps. If you pass --min-coverage N, the overall percentage is rounded to two decimals and compared against your threshold, exiting 0 when it’s met (or when no threshold is set) and 1 when it falls short. Report colors follow the same PASS/SKIP/FAIL vocabulary as run-tests.
Example output
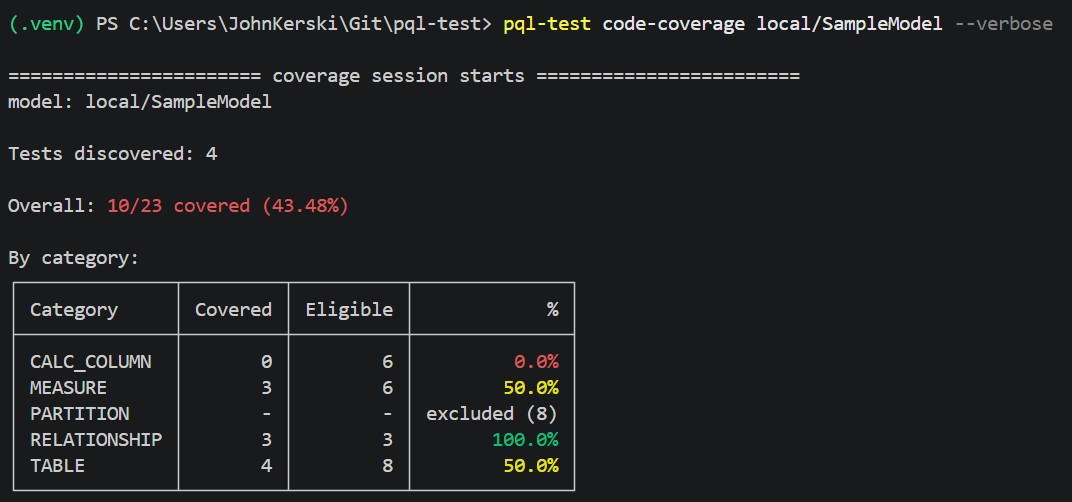 Figure 1 -
pql-test code-coverage output
What this does not mean
A high score only proves objects are referenced by a test, not that the test’s assertions meaningfully validate their behavior. A test that checks “table has more than zero rows” and a test that validates every business rule on that table both count as “covered” identically.
Treat a low score as “nothing here has been tested at all,” and a high score as “at least referenced by a test,” not a correctness guarantee.
Learn More
I’d love to hear what you think of this approach to code coverage for semantic models. Check out pql-test, PQL.Assert on DAXlib, or the PQL.Assert GitHub repo to get started, and let me know your thoughts on LinkedIn or Twitter/X.